Cracking the PSP GPU's transform and raster

After the VFPU math functions were cracked, I figured, let's try the same with the GE, the PSP's GPU. PPSSPP has a software renderer, mostly used as a reference, and for debugging. It's long been pretty close to accurate, but that isn't good enough for a reference, and some games really depend on the details: depth fighting in the distance, banding in fog, a seam in a sky box, a lens flare that reads back the depth buffer.

So I pointed Claude at it again, with a real PSP hooked up over USB like the last time, and let it write its own test programs for the hardware. It ran a bit over 170 experiments on the PSP. When it was done testing and applying fixes, the software renderer reproduces 125 of a set of 132 frame dumps from various games, bit-exact pixel by pixel against the same dumps played back on a real PSP.

Claude has extended my GE documentation with the findings from this project GPU section of the docs, starting with the new page on GE arithmetic.

This is the pull request implementing all this.

Below is Claude's own writeup.

Claude says

The GE is a fixed-function GPU: transform and lighting, a clipper, a rasterizer, texturing and blending, all configured with a display list. That makes it a black box with a lot of inputs and only a few visible outputs, the color and depth buffers. The job was to explain every bit of those outputs, for any input.

The VFPU work had an oracle: fp64's tables gave the exact answer to every input, on a laptop, in a second. Here there was no oracle except the PSP itself. Every question had to be turned into a display list, run on the hardware, and read back.

The setup

The tool for that is geprobe. It builds GE display lists on the host from a Python description, sends them to a small PRX on the PSP over PSPLink, and reads the framebuffer and the depth buffer back. A probe is a job: some vertices, some state, a readback.

The main difficulty is that the GE's outputs are narrow. A color channel has 8 bits and depth has 16, while the values inside the pipeline are floats with much more precision. So most of the work was designing readouts that carry the bits you want to see:

  • Points as samples. A point primitive lights one pixel with its exact depth and color. Drawing a Bezier patch as points gives every tessellated vertex its own pixel.
  • Depth windows. Setting the viewport so that a tiny range of z covers all 65536 depth values reads a transformed z down to its last bit.
  • Texture ramps. A texture whose texel value is its own position, sampled with bilinear filtering, shows where a pixel's texture coordinate landed in 1/16 of a texel.
  • Using one unit to read another. The texture matrix can take the normalized normal as its input. With the matrix scaling the interesting part up, the texture coordinate carries every bit of the GE's normalization. Shade mapping turns a light vector into a texture coordinate the same way.

The other half was a replayer. PPSSPP's frame dumps record everything a game sent to the GE for one frame. The pspautotests repository has a tool that plays a dump on a real PSP and captures the result, so every dump became a test case: the software renderer's output against the PSP's.

Floats, but not IEEE

Details: GE arithmetic, the vertex pipeline.

The first thing to fall was the number format. Display list parameters are 32-bit floats with the low 8 bits cut off, and it turned out the GE also computes in that format: a 16-bit significand, and truncation toward zero everywhere.

That alone wasn't enough, because how the operations are built matters as much as the precision:

  • The adder has no guard bits. Both operands are truncated to the precision of the larger one before adding. So adding a small offset to a large value loses the offset's low bits, before the sum is ever rounded.
  • A matrix row is one sum. No order of pairwise additions fits the data. The hardware forms the four products exactly, truncates each of them to the precision of the largest one, adds them exactly, and truncates once. The same unit combines the world, view and projection matrices before any vertex is transformed, and computes dot products, the texture matrix and the vector to a light. If that sounds familiar from the VFPU post, it should: the VFPU's vdot, as fp64 worked out, aligns and sums its terms the same way, with no order between them. It's the more careful design of the two, keeping guard and sticky bits on its products and rounding the final sum to nearest, where the GE just truncates.
  • There's no divide. The perspective divide multiplies by a reciprocal from a table of 128 linear segments. Normalization uses a reciprocal square root with the same layout. Neither is the VFPU's interpolator, which is quadratic.

A second reciprocal

Details: the raster pipeline.

The rasterizer was the biggest surprise. Depth isn't z/w per pixel, and it isn't walked along edges like on the PS2 either. Each triangle gets fixed-point planes for its depth, color, fog and texture coordinates. The setup divides by the triangle's area with a third table, finer than the first two: 256 segments of 16-bit indices.

Fitting that table took a while, and finishing it took games. The probes pinned most segments, but left a few with a window of possible values. Blade Dancer's depth needed one of them at the top of its window, and a single Gouraud-shaded test triangle, with 37 pixels off by one, needed another. Both landed on the same formula as nearly all the others: the exact reciprocal at the segment start, rounded down to a multiple of 16. The table's starting values are now that formula, except for the first segment.

With the planes, depth, colors and texture coordinates all fell into place, including details nobody would guess:

  • the plane is anchored at the leftmost vertex, unless the long edge is the triangle's right side;
  • the mip level uses one q per 4-pixel span, taken at the span's second pixel in the direction the row is walked;
  • a 1:1 bilinear sprite only lands exactly on texel centers when its area is a power of two, since the gradient is a fixed-point reciprocal of the area.

Lighting

Details: GE lighting.

Lighting had a known bug report behind it: the hair shine in iDOLM@STER SP looked wrong (#12376). The specular half vector uses a viewer direction taken from the view matrix's third column, not (0, 0, 1). The specular power is Mitchell's approximation, straight lines between powers of two, with the exponent cut to 4 mantissa bits. And light colors are scaled by 8-bit factors with ((2x + 1)(2s + 1)) >> 10, which turns out to be the same product the blender uses.

The last lighting bug came from a single vertex in Syphon Filter (#13568), whose spot factor was 33 on the PSP and 32 in the emulator. The GE never forms a world-space position for lighting. The vector to the light is one row sum, of the light position minus the world translation and the model position times the world matrix.

Curves

Details: curves.

Bezier and spline patches turned out to be evaluated without floating point arithmetic, even though every control point is a float.

De Casteljau's algorithm evaluates a Bezier curve with nothing but linear interpolation. Take the four control points, lerp each neighboring pair at the parameter t, and you have three points; lerp those, and you have two; lerp once more, and you're on the curve. A patch does that for each column of control points, then once more along the row of results. So the whole evaluation is a few dozen lerps, a + (b - a) · t.

The GE does each lerp as integer arithmetic. It looks at the two operands' exponents and takes the larger one, then writes both operands as 16-bit integers in units of that exponent's lowest bit, truncating whatever doesn't fit. The parameter t is an 8-bit fraction, k/256. The lerp is then A + floor((B - A) · k / 256) on those integers, and the result is a float again, at that same exponent. Lerping 1.5 and 0.001, for example: at 1.5's exponent, the lowest bit is 2^-15, so 0.001 becomes 32 units (0.0009765625) before anything else happens, and the result can't carry more precision than that. The fixed point is chosen anew for every lerp, which makes it a kind of block floating point: an alignment shift, an integer multiply by k, and a truncating shift, with no normalization in between.

At k = 0 and k = 256 the lerp passes an operand through untouched instead of truncating it, and that detail decides the normals at patch edges, which come from the tangents. With all of that, Coded Arms (#21391), Pursuit Force (#11216), Test Drive (#21763) and LocoRoco have exact depth.

Oddities

Details: the raster pipeline.

A few things are hard to call anything but quirks:

  • A triangle taller than about 2730 pixels lights extra pixels along its long edge, one per 4-pixel span, as if a 17-bit field overflowed.
  • The REGION1 register, which looks like a clip rectangle, translates the drawing. For odd x offsets it also reverses each group of 4 pixels.
  • A pixel drawn past the framebuffer's stride lands at the start of the next row.

The texture cache

Details: the texture cache and self-texturing.

The GE reads textures through an 8 KB cache that the GE's own drawing doesn't update, which is normal for a GPU of this generation. It only shows when a game textures from the buffer it's drawing to, as bloom and blur passes do. A texture that fits in the cache stays there until the next TEXFLUSH, across draws, so a game that blurs a small buffer onto itself several times reads the first pass's input in all of them (Final Fantasy Type-0, #20104). Larger self-textures are mostly read as they were before the draw, in 8-row blocks loaded the first time a primitive needs them.

Bugs that weren't the GE

Many differences between the emulator and the PSP turned out not to be the GE at all:

  • The replayer had bugs. Its list buffer could wrap and let the GE run a lap of stale commands, which drew a screen-filling skinned triangle that wasn't in the game. It also didn't wait for the GE to finish before CPU and DMA writes to VRAM. Fixing those made several "unexplained" dumps exact without touching the emulator.
  • The software renderer had a race. I spent a probe on a theory that the GE caches recently written pixels, to explain a blur in Tokimeki Memorial 4 (#6379). The probe showed the PSP simply draws in order. The rows that differed changed from run to run in the emulator, because two of its rendering threads raced over pixels past the buffer's stride.
  • Merging primitives changes the result. The software renderer merged adjacent sprites, and drew rectangles made of two triangles as one sprite, for speed. Since every primitive has its own planes, both changed which texels were sampled.

What came out

Game frame dumps exact against the PSP125 of 132
Framedump tests (frametests.py) exact29 of 30
Hardware probesabout 174

The rest are known cases:

  • Swizzled depth reads. These dumps read the depth buffer through its swizzled mirrors, which we deferred. Fixing those is next.
  • Lazy texture loading. Two self-texturing effects depend on the GE loading textures in 8-row blocks, which isn't modeled yet.

Three dumps used to hang the PSP's replayer, which looked like a GE problem and wasn't: old dumps packed their data unaligned, which the PSP's CPU faults on, and one restored a CLUT load from an address that was only valid in the game. With the replayer fixed, all three are exact.

All of the arithmetic lives in one file, GPU/Software/GEMath.cpp, with unit tests. A selection of the experiments became pspautotests, gpu/exact, recorded on a PSP, so a change that moves the renderer away from the hardware shows up in the tests.

Lessons

  • Design the readout first. Each probe was only as good as the number of bits it could get out of the GE. Most of the breakthroughs came from a new way to read something out, not from a new hypothesis.
  • Fit to the probes, then to the games. A table fitted to synthetic tests is right where the tests looked and loose everywhere else. Game dumps found the loose spots.
  • Suspect the pipeline around the hardware. The replayer and the emulator's own threading each produced differences that looked like GE behavior.
  • The hardware is cheap, in the hardware sense. Whenever a hypothesis needed per-pixel floating point math, it was wrong. The right answers were always the cheap ones: tables, truncation, narrow fields, shared units.
  • Be nice to the PSP. A readback that's too big or two jobs at once wedges it until someone resets it by hand.
Cracking VFPU math functions using AI

The PSP has a vector unit, the VFPU, which is set up as a traditional MIPS co-processor that shares the instruction stream with the main CPU, but has its own pipeline. Much like modern GPUs it has a special function unit, for functions like sin/cos, exp2/log2, square root, reciprocals, etc. It has long been know exactly what these instructions do, but not how they do it - they all return approximations made in an unknown way, none of them return the correctly rounded IEEE result.

  • vrcp (reciprocal)
  • vrsq (reciprocal of square root)
  • vsqrt (square root)
  • vexp2 (pow(2.0f, input))
  • vsin (sin, with 4.0 = one lap instead of 2*PI)
  • vcos (cos, with 4.0 = one lap instead of 2*PI)
  • vasin (arc-sine, same 4.0 circle system)
  • vlog2

There's also vrot which is a convenience function for sin+cos for building rotation matrices.

fp64, a long-term contributor to the project, has already implemented bit-exact versions of these (#16984, etc), by dumping the full result tables from a real PSP and adding correction tables on top of close approximations. This costs multiple megabytes of memory though, and some performance - it would be much neater if we knew the underlying functions. fp64 has also implemented a bit-exact version of the VFPU's dot product instruction, which really deserves its own article.

Encouraged by skmp's work reversing similar instructions on the Sega Dreamcast, Reversing the SH-4 fpu with the help of three AI models, I thought I'd simply set Claude on it.

And lo and behold, it worked. It took Claude Opus 5.5 about an hour.

This will save PPSSPP a few megabytes of shipped tables in future versions, and we will enable accurate emulation of these functions by default due to the somewhat faster performance than the previous method.

The pull request: VFPU: Replace fp64's correction tables with accurate implementation of special functions.

Below is Claude's own writeup (very lightly edited) about how it did it.

Claude says

PPSSPP has had the functions bit-exact for a while, thanks to fp64's work in issue #16946. The method was careful measurement: an easy-to-compute base approximation, plus per-64-input correction deltas, plus lists of exceptions. It shipped as about 4.9 MB of .dat binary files. That's the right way to get correct answers when you don't know the algorithm. It also leaves an itch: the hardware certainly doesn't have 5 MB of ROM for this. What does it actually do?

This post is about finding that out, one function at a time, without ever looking inside the chip. The answer turned out to be a single, rather textbook circuit. All eight functions now come from about 10 KB of coefficients, bit-exact over every one of the 2^32 float inputs.

The setup

fp64's code is an exact oracle. It agrees with the hardware on every input, and it runs in a second on a laptop. So I could dump every output of every function, for example all 2^23 mantissas of 1/x over [1, 2), and interrogate the data as much as I liked. Before relying on that, a new hardware test (pspautotests cpu/vfpu/exact) ran special values and exponent sweeps on a real PSP. It agreed with the oracle, and showed a few mismatches in the other CPU backends along the way.

The other tool that mattered was exhaustive checking. A hypothesis about a 23-bit function isn't right until it reproduces all 2^32 inputs. That takes 30 seconds, so there's no excuse.

First attempts: good enough isn't the answer

The obvious guess is a piecewise polynomial. Fit a quadratic to each chunk of 1/x and see how many outputs come out exactly right. The answer was about 93%, whatever chunk size or polynomial degree I tried. Fitting coefficients that are floats and evaluating them with the VFPU's own dot product, which has its own exact rounding rules, got about 92%. One suggestion from Henrik was that the functions are built out of vdot operations, since on the Dreamcast the FIPR inner-product unit turned out to be reused by the function approximator. That was a good lead, but a single vdot of float coefficients also stalled at 92%.

The failures had a consistent shape. The best possible real-valued quadratic missed by about one 24-bit ulp, in a band exactly one ulp wider than the output's truncation window. Something discrete was going on underneath, and least-squares fitting would never find it. I switched to feasibility instead of fitting: for a candidate formula, can any coefficients reproduce every output exactly? Each output then turns into an interval constraint on the unknowns, and intervals intersect cheaply. This question, rather than "how close can I get", drove everything after it.

Finding the segments

The first structural question was how many pieces the function is made of. Within every run of 64 consecutive inputs, the output is exactly a straight line. Past that, I checked how many of those 64-input intervals can share one slope. The answer was 1,024 intervals, which is 2^16 inputs, and never 2,048. So the top 7 bits of the mantissa pick one of 128 segments. Within a segment the slope is shared, and it equals the true derivative at the segment's centre. That's the textbook layout of a hardware quadratic interpolator: a small table indexed by the top bits, plus arithmetic on the rest.

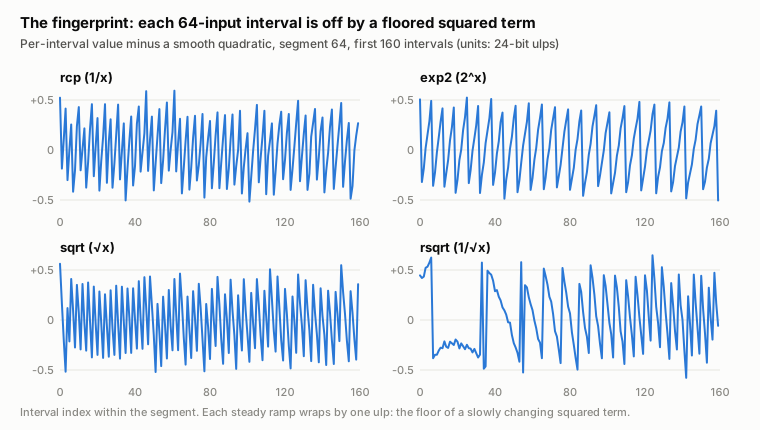
The fingerprint

With the slope pinned, each 64-input interval still carried its own offset. Subtracting a smooth quadratic from those offsets left this:

Sawtooth of per-interval errors for rcp, exp2, sqrt and rsqrt

It's a sawtooth, one ulp tall, and the same in every function. The rate at which each ramp climbs matched something specific: the local slope of that function's squared term. For rcp that's −0.273 ulps per interval, and the ramp climbs 0.28. For exp2 it's −0.151, and the ramp climbs 0.15. rsqrt's ramp looks different, but its slope of −0.958 aliases to a small drift, exactly as a floor would make it.

So the squared term is floored to whole ulps on its own before it is added in. The linear term isn't floored with it, and neither is the total. That's also why no polynomial could fit: a floor with its own phase is invisible to least squares.

A long detour, and some bugs of my own

Knowing that the squared term is floored didn't immediately say how. I tried floors with a phase and floors at quarter and half ulps. I tried truncated squarers that drop low partial products, split squarers, squarers keeping only 12 significant bits, and two-step products. All of them came out at the same wall: 99.65% of outputs right, with the rest one step off, at points where the squared term sat within about 0.015 ulp of an integer.

Several of the dead ends were my own bugs. One search stepped a coefficient so coarsely that it could never hit the true value. One extraction subtracted a constant twice. A zsh quirk made one parameter sweep silently test nothing. When a hypothesis fails cleanly, the right move is to check the checker first.

The break: identical margins

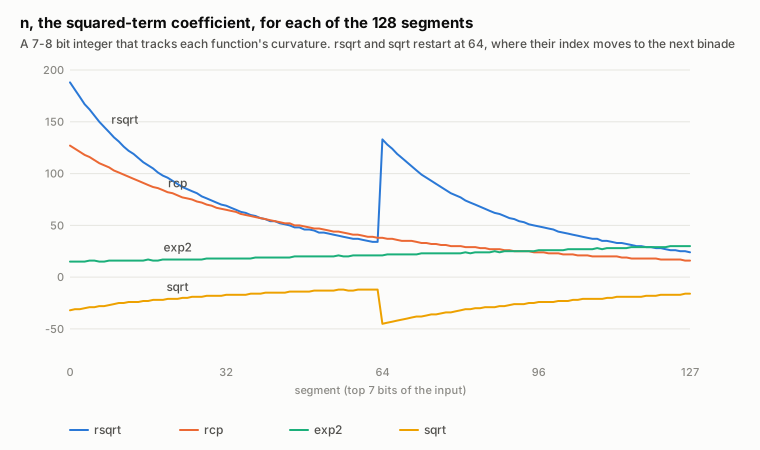
What broke it open wasn't a new hypothesis but a coincidence in the output of a sweep. I fitted every segment of rcp separately and printed the best-fit squared coefficient and its error margin. Neighbouring segments often showed identical values to four decimals, for example segments 115 to 120 of rcp all at 143.9636. Identical decimals meant identical integer data.

Two things followed. The squared coefficients are all multiples of 8/2^20, so the coefficient is a small integer n, with a squared term of n·t²/2^17. And the per-interval integer sequences were byte-for-byte identical across functions: exp2's segment 32 matches rcp's segment 116, and rsqrt's segment 100 matches rcp's segment 54. The squared-term circuit is one unit shared by all of them, and its output depends only on n and t.

Squared-term coefficient per segment for rsqrt, rcp, exp2 and sqrt

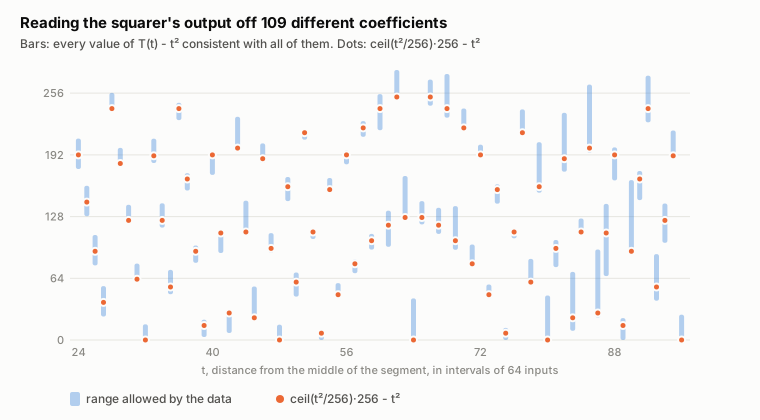
That turned the squarer from a guess into a measurement. With 109 different values of n in the data, I could solve for the squarer's output T(t) directly. For each t, each n constrains T(t) to an interval, and 109 intervals intersect very tightly:

The squarer output recovered from data, against ceil(t squared over 256) times 256

The squarer rounds t² up to a multiple of 256. With that, the squared term is (n · ⌈t²/256⌉) >> 9, and it matched every n and every t with zero mismatches.

The model for a segment is then:

t = |(x2 >> 6) − 512|
v = c0 + ((m · x2) >> 17) + ((n · ⌈t²/256⌉) >> 9)
result = v & ~3   (in ulps of the segment's exponent)

Here c0 is a whole number of ulps, m has about 18 bits and n has 7 to 8. For each segment and each candidate (m, n), every output pins c0 to an interval, so fitting a segment is a scan over a few thousand m values. All 512 segments of rcp, rsqrt, sqrt and exp2 fit. The resulting code matched fp64's over all 2^32 inputs on the first run, apart from one bug in the wrapper arithmetic.

sin: counting backwards

sin didn't fit, at any segment size. The clue came from its few non-monotonic outputs, places where the output steps the wrong way. For rcp those only happen between inputs 64k + 63 and 64k + 64, at the interval boundaries. For sin they happen one input later, between 64k and 64k + 1. That's what you get if the hardware counts from the other end. It indexes the quarter wave with y = 2^23 − x, which amounts to computing sin as the cosine of the complementary angle. Re-indexed that way, the same interpolator fits.

What remained was scale. Most of sin's range is below 0.5, and some segments cross into a lower binade partway through. The rule turned out to be simple. Each segment works in the ulps of its first, largest output, and truncates to 4 of those even for results that drop into the next binade down. asin confirmed it from the other side. Its values rise within a segment, so results that climb into the next binade keep one extra bit. Those are exactly the 1.25% of asin outputs with 23 significant bits instead of 22.

log2: the hardest one

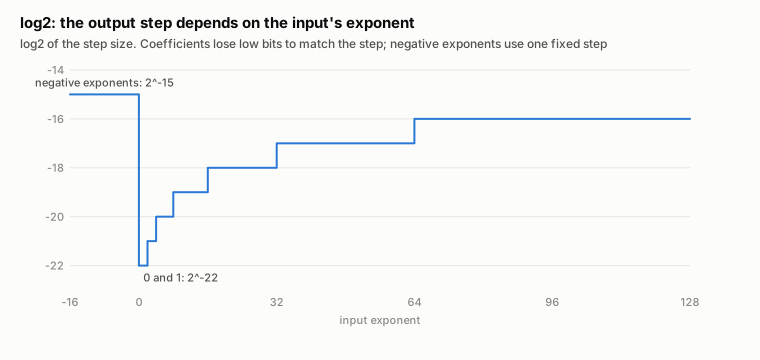
log2 for inputs in [1, 4) fitted immediately. For larger inputs, and for inputs below 1, it didn't. The result is exponent + log2(1.m), and as the exponent grows it takes up bits the fraction can no longer use:

log2 output step by input exponent

Every hypothesis about how the hardware reaches the coarser step failed for a while. The outputs below 1 looked like a different, less accurate computation altogether. The resolution was that the datapath cuts the coefficients down to match the output's precision. At level d, where the step is 2^(d+2) units:

  • the slope m loses its low d + 2 bits;
  • the squared coefficient loses the low d bits of its magnitude;
  • c0 absorbs the part of the squared term that was dropped, as evaluated at the segment's edge.

For negative exponents that is level 7, with a step of 2^-15. There the squared term disappears entirely, which is why that path looked like plain linear interpolation. The sum is truncated toward zero, which rounds negative results up. That single rule also covers the region just below 1.0 that fp64's code handled as a special case, including the sign of −0.

What came out

TablesInterpolator
Data4.9 MB loaded from assets/vfpu10.5 KB of static const coefficients
rcp4.2 ns3.6 ns
rsqrt5.4 ns3.6 ns
exp26.3 ns3.9 ns
log27.1 ns5.1 ns
sin14.6 ns5.9 ns
asin6.0 ns3.6 ns

All are bit-exact over every 32-bit input. vrot needs sine and cosine together, and sharing the argument reduction makes the pair about 10% faster.

What does this say about the chip? It's the design from the literature on hardware function evaluation, for example Piñeiro, Oberman, Muller and Bruguera's minimax quadratic interpolator, or NVIDIA's multifunction interpolator (Oberman and Siu, 2005), which covers much the same set of functions. It has a 128-entry ROM per function, a squarer that sees only the top 10 bits of the offset, and coefficient widths trimmed to what the output needs. Whether the final adder is shared with vdot, as on the Dreamcast, can't be told from outputs alone. The separately truncated products are certainly compatible with it.

Lessons

  • An exact oracle plus exhaustive checking beats cleverness. Every idea here was cheap to test against all 2^32 inputs, so wrong ideas died quickly.
  • Ask whether it's possible, not how close you can get. Least squares hid the discrete structure. Interval feasibility exposed it.
  • Watch for suspicious coincidences. Identical margins across segments was the single most useful observation. It came from output I wasn't looking for.
  • Suspect your own tools. Several "impossible" results were bugs in my search code.

PPSSPP 1.20.3 - all sorts of improvements!

PPSSPP 1.20 is here - or actually 1.20.1, due to a build system mishap I had to increment the version immediately. Get it on the download page for PC or Mac! If you're on Android and already have it installed from Google Play, your update will arrive within a week (to catch crashes early).

PPSSPP 1.20.3 has now been rolled out, with some important bugfixes, including the iOS multitouch bug and background setting bugs. 1.20.2 also introduces an improved ad hoc server list.

See the detailed list of changes since the 1.19.x series, and the 1.20.x updates.

iOS bug alert!

The iOS version 1.20.1 has broken multitouch in OpenGL mode. Update to the latest instead.

Download now!

Read more »

PPSSPP 1.19.3 - new bugfix release

Another bugfix update to 1.19, called 1.19.3 is out now!

As always, if you installed from Google Play on Android, or App Store, just wait for the update, it's coming. The release is being slowly rolled out over a week to catch any unexpected issues.

Download now!

Changes in 1.19.3

1.19 was a big change, as described in the release announcement. Atrac3+ music playback, which is a fundamental feature in a lot of games, got a big improvement, leading to many compatibility fixes.

Whenever you make a big change though, it's inevitable that something obscure breaks - in this case, Atrac3 (not +) files generated by other apps than the one used in games failed to decode, due to a broken first packet. This packet should be skipped, but our calculations for that weren't quite right, and neither were the old ones, but they were wrong differently! So previously, it had actually just worked by accident.

This affected a number of game modifications that many people like to play, such as a Crazy Taxi mod that adds back the proper music from the Dreamcast original, and also a number of modified football (soccer) games which lost their music and commentary.

Anyway, now that's fixed and tested on hardware for correctness, and likewise a bunch of other bugs that slipped through previous testing have also been taken care of. For details see the new section in the 1.19 release announcement, linked above!